PHP2Shell: The Warning Was Early. The Response Was More Complicated.#
Two critical vulnerabilities, one instinct to pull the plug, and a reminder that security is a technical discipline.
On 21 October, two critical PHP vulnerabilities put organisations on alert. My morning started with an internal warning to the technical teams in my business unit. At 08:18, I formally reported the issue through our information security process, including recommendations for identifying exposed systems and preparing mitigations.
The response I received was not quite what I expected.
The ticket was closed#
The vulnerabilities were being discussed under the name PHP2Shell, with a reported CVSS score of 9.2 and potential remote code execution. A PHP security release was expected at 16:00 CEST. Some details circulating online remained unverified, so my report distinguished confirmed information from speculation.
I recommended identifying PHP installations, checking versions and patch ownership, prioritising internet-facing systems, and preparing temporary mitigations. I also pointed out that updating WordPress does not update the underlying PHP runtime.
The response from central security leadership was that vulnerability information already arrived through national cybersecurity and vendor channels. I was asked not to send similar general notifications in future. Central IT, I was told, no longer developed applications in PHP. The ticket was closed.
That misses an important distinction. Receiving an advisory is not the same as knowing where you are vulnerable. Someone still needs to identify the affected systems, establish ownership, assess exposure and decide what to do.
A threat feed cannot do that for you.
Pull the plug?#
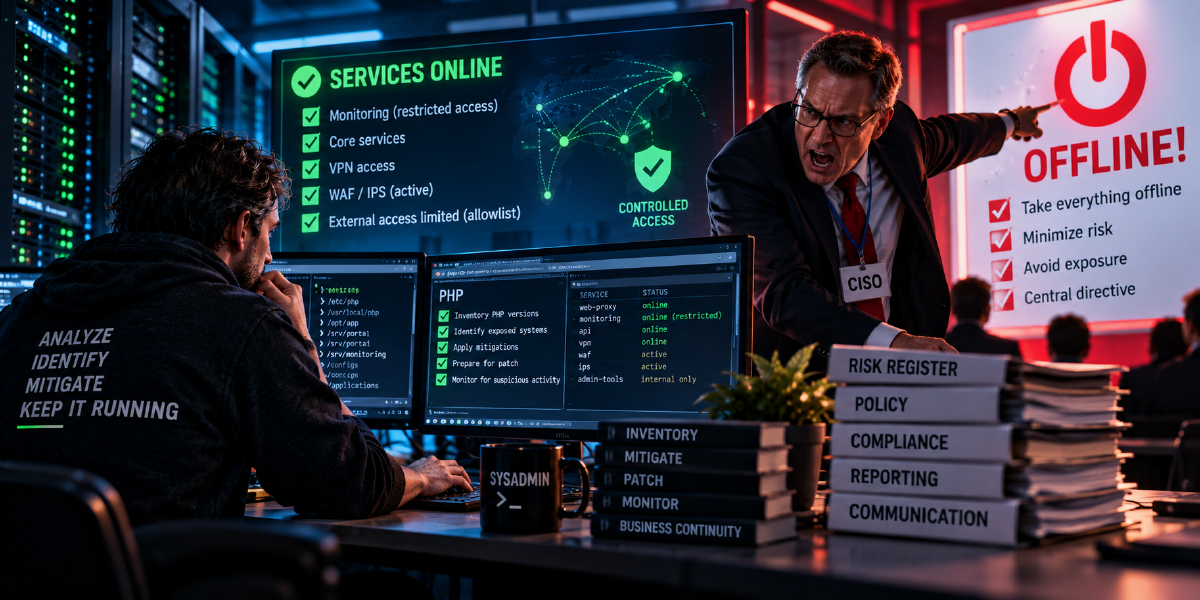
At 10:45, central security leadership asked business unit security representatives to establish where PHP was used and which applications depended on it. The message also proposed taking internet-facing PHP systems offline until patches became available.
The earliest publication I could find on the national cybersecurity community platform appeared at 11:03, followed by a government announcement at 13:59.
I cannot establish which information channels the organisation had received earlier, or whether my report triggered the 10:45 message. The timeline does, however, raise questions about the difference between dismissing a report and acting on the risk it describes.
Taking exposed systems offline can be the right decision. If you cannot establish what is vulnerable and the potential impact is severe, removing the exposure may be the safest option. But it is not automatically the only option.
The decision should depend on the actual exposure, the available controls and the consequences of interrupting the service.
Online, with tighter controls#
Within our business unit, additional technical measures were reported to reduce exposure while keeping the monitoring service operational.
External access to the customer monitoring dashboard was restricted to approved IPv4 addresses. Administration tools that did not need public access were moved to internal-only access. Geographic filtering was applied at the reverse proxy, alongside existing web application firewall and intrusion prevention controls.
Customers were informed about the access restrictions and how to request access for their public IPv4 addresses. Existing VPN access remained unchanged.
This did not prove that every PHP component had been identified, nor did it replace the need to patch vulnerable software. It did reduce the externally exposed attack surface while the response continued.
The service stayed online. Access was simply more restricted.
That is the point of engineering a mitigation rather than treating availability and security as mutually exclusive. Sometimes you need to pull the plug. Sometimes you can reduce the risk without taking the service down. Knowing which option makes sense requires technical understanding.
We don’t develop PHP#
The argument that an organisation no longer develops applications in PHP is not particularly reassuring. Not writing PHP code does not mean you are not running it.
Third-party applications, monitoring platforms, administration panels and customer portals can all depend on PHP. You may not own the source code, but you still operate the software and inherit its risks.
Your attack surface does not stop at your own repositories. It includes the software you deploy, the runtimes it depends on and the services exposed to the internet.
Security awareness goes both ways#
There is another contradiction here. Employees are expected to complete annual cybersecurity assessments and training. People in security roles face additional expectations, including Silver and Gold training.
The message is clear: recognise risks, challenge assumptions and report concerns through the proper channels.
That expectation has to work both ways. If someone follows the process and submits a report with concrete recommendations, dismissing it because the general information is already known sends the wrong message.
Not every report needs to trigger an incident. Not every warning will be new. But the response should address the actual risk. Are the affected systems known? Is somebody responsible? Are mitigations underway? If no action is needed, explain why.
Otherwise, the reporting process becomes paperwork rather than a security control.
Leave security to the techies#
My personal takeaway is blunt: leave security in the hands of the people who understand the technology.
Governance, policies and risk registers have their place. Someone needs to set direction, manage responsibilities and verify that risks are addressed. But reporting is not remediation, and compliance is not the same as security.
A risk register does not patch a server. A policy does not restrict an exposed endpoint. A closed ticket does not mean the problem is solved.
The engineers running the systems understand their dependencies, their exposure and the practical options for reducing risk. Let them lead the technical response. Let governance support that work, challenge it where necessary and verify the result.
I would rather see a technically sound mitigation that keeps a service running for an approved audience than a reflexive shutdown that treats unavailability as proof of security. That is not an argument for keeping everything online. It is an argument for making informed decisions.
Security is not the paperwork around the work. It is the work itself.